Get Appointment
- contact@wellinor.com
- +(123)-456-7890
Blog & Insights
- Home
- Blog & Insights
The demo: a returns desk with one hard question
A customer asks to send an item back. They name the order and the item, and either pick a reason from a list or explain in their own words, often with a photo. Larkfield has to decide whether to refund, replace, deny or escalate, and who pays for the return. Almost all of that is policy, and policy is a table. The return window, which categories can come back, when a photo is required, the per-quarter limit, the fee: each fits in a cell. Only one question has no cell, because nobody typed the answer into a field: who is responsible for the problem? Was it the retailer, the carrier or the customer, or is it unclear? Answering it means reading what a person wrote and looking at what they photographed. We used one test to draw the line. If an intern could write the rule in an afternoon from the policy document, it is code. If the answer depends on reading what a person wrote or looking at a picture, it is the model.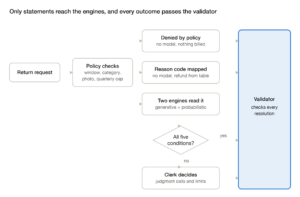 How a return request moves through the desk Policy turns away or settles most requests before a model is involved; only a customer's own words reach the engines, and nothing takes effect until the validator has checked it.
What the rules handle: most of it, for free
Every rule Larkfield has lives in one small JSON file that fits on a slide. It sets a 30-day window counted from the carrier's delivery date, three returns per customer per quarter, and categories such as perishables and final-sale items that can't come back at all. A table says, for each category and responsible party, which outcomes are allowed, what fee applies and who pays return postage. Policy checks every request before any model sees it, and many never go further:- A clearance throw blanket marked final sale is denied because final-sale items can't come back. No model is called and nothing is billed.
- A jacket returned 47 days after delivery is denied on the window, with a reply that cites the rule.
- A T-shirt returned with the reason "changed my mind" maps straight to the customer, who gets a refund. There is nothing to read, so no model is needed.
What the models handle: one question, asked two ways
When a customer explains in their own words, the request goes to two engines on Microsoft Foundry, both running the same model. They are asked exactly one question: who is responsible?- The generative engine reads the statement and the photo. It answers with a responsible party, a one-sentence reason for the clerk, a draft reply to the customer, and any flags it noticed, such as damage in transit or possible abuse. Its output follows a fixed schema, so the code never parses free text.
- The probabilistic engine uses Foundry's Decisions API to return a probability for each of the four parties and a confidence, with no prose. The probability for the named party is what lets policy set a floor for trusting the answer.
Guardrails: the engines read, the code decides
A request is approved without a person only when every condition in policy holds:- Both engines name the same responsible party.
- The probabilistic engine gives that party at least 80%.
- The refund is $75 or less.
- No blocking flag is raised, such as possible abuse or signs of use.
- The customer is under their per-quarter limit.
Measuring it: labeled requests, not impressions
A model in a business process needs a number behind it, not a good feeling from the demo. Returns Desk ships with 46 hand-written requests whose answer is already known. Forty include a customer statement, ten for each responsible party, written with the variety real customers bring. The other six carry only a reason code. An evaluation runs both engines over every labeled request. It reports how often each engine named the known party, a grid of known party against named party, and the cost per request. In production, each resolution a clerk confirms would become a new labeled request, so the measurement could grow with use. The demo only re-scores its own sample set. Two choices kept it honest. We wrote the statements by hand rather than generating them, so the test doesn't measure how well one model reads another model's writing. And we left out claims about how well-calibrated the probabilities are, because 40 requests are too few to support them. That makes the 80% floor a starting setting, not a proven one. Tune it against labeled requests before trusting it with money.What changes at enterprise scale
The split between rules and model holds at any size. What a production rollout adds is everything around it:- Requests arrive from the returns portal and the contact center. Approved refunds go to the payment platform, and carrier cases go to a claims process instead of stopping at a label.
- Identity and audit. Every resolution records which clerk approved it, from the same sign-in that guards the board. Policy changes go through change control like any other release.
- Many clerks work the queue at once, and the resolution log lives in a database rather than a file. Engine calls are made only for requests with a statement, so cost grows with the share of returns that need reading, not with total volume.
- Measurement on real returns. The engines are evaluated on the retailer's own labeled returns. Auto-approval runs in shadow mode first, logging what it would have done next to the clerk's decision, before any limit is raised.
Takeaways for your own processes
The pattern carries well beyond returns: claims, support tickets, invoice exceptions, access requests. Wherever a person's words meet a set of rules, the same split applies.- Find the one question. List every decision in the process and apply the intern test. Usually only one or two need a model.
- Put the rules in data. A policy file the business can read and edit beats rules buried in a prompt, and it costs nothing to run.
- Ask the model for an input, not a decision. A responsible party with a reason is something code and people can check. A finished outcome isn't.
- Let code bound the risk. Caps, allowed outcomes and arithmetic checks hold no matter what the model says or what a customer writes to it.
- Keep a person on the hard cases. Automation should clear the easy, agreed, low-value requests, so the clerk only sees what needs judgment.
- Measure before you trust. A labeled set and a repeatable evaluation turn "it seems to work" into accuracy and cost per request.
Try it yourself
Returns Desk is open source under the MIT license at github.com/keyva/returns-desk.- No cloud account: clone it and run the tests. They use canned engine answers and never call Azure.
- The full demo: you need an Azure subscription, uv and OpenTofu. The included OpenTofu sets up the Foundry resources with Microsoft Entra ID sign-in and API keys turned off. The README walks through running the board locally and deploying it to Azure Container Apps. The hosting steps haven't been run end to end yet, so treat them as the intended order rather than a tested script.
Part 3: Proving It Works
Parts 1 and 2 covered why this matters and how the runtime got healthy. But a healthy runtime isn't the same thing as a proven one. The only claim worth making to a test team is “your actual test suite will pass here,” and that took three separate checks, each one harder to fake than the last.Check 1: Does the sandbox even work
Simplest possible test: a pod pinned to runtimeClassName: sysbox-runc, scheduled onto a labeled node.apiVersion: v1 kind: Pod metadata: name: sysbox-test spec: runtimeClassName: sysbox-runc nodeSelector: sysbox-runtime: running containers: - name: test image: ubuntu:24.04 command: ["/bin/bash", "-c", "cat /proc/self/uid_map; sleep 3600"]A real user-namespace mapping, something like 0 100000 65536, confirms the pod is running in its own isolated UID range and not sharing the host's root. If this doesn't show up correctly, nothing past this point matters.
Check 2: Does nested Docker actually pull and run something
This one runs /sbin/init as the entrypoint, which is required so the nested, systemd-managed Docker daemon actually comes up inside the sandbox, with hostUsers: false and a Docker client config mounted in for the internal registry.kubectl create secret generic docker-config-ar \ --from-file=config.json=./docker-config.json \ -n defaultOne thing bit us here that's worth calling out on its own. A placeholder credentials file (anything with a literal “{AUTH}” string still sitting in it) mounts into the pod just fine. No error. Looks correct. Then every single nested pull fails, and the failure message doesn't point back at the credential at all. The secret needs a real base64-encoded oauth2accesstoken entry, generated fresh, because Artifact Registry tokens are short-lived. That has to be part of whatever rotates credentials automatically, not something set once and forgotten. Second gotcha, smaller but just as annoying: pulling a public Docker Hub image through a virtual repository requires the /library/ segment for official images. docker-remote/hello-world fails. docker-remote/library/hello-world works. One path segment, and it cost real debugging time before anyone remembered the convention. Once both were right, a pull-and-run against the internal registry succeeded and printed the expected Docker Hub greeting. That's proof the nested daemon itself works, not just the sandbox around it.
Check 3: Does the library actually work, not just the daemon
This is the check that matters most and gets skipped most often. Nested Docker working doesn't mean Testcontainers works, because Testcontainers talks to Docker through its own bundled client, and that client can disagree with the daemon about API versions even when the daemon is completely fine. That's more or less exactly what happened: an older Testcontainers dependency threw client version 1.32 is too old. Minimum supported API version is 1.40, while the nested daemon was sitting there healthy on API 1.55. Nothing wrong with Sysbox, or with Docker. The client shipped inside the old Testcontainers jar just hadn't caught up. The fix was pinning the test application to a current Testcontainers release, 2.0.5, with a client that actually negotiates a modern API. The final proof was a small Java app, built into a fat jar with Maven, that pulls a base image through the internal repo, starts a container, runs a command inside it, and prints a marker on success:docker run --rm \ -v /var/run/docker.sock:/var/run/docker.sock \ -v /root/.docker:/root/.docker:ro \ -e DOCKER_CONFIG=/root/.docker \ -e DOCKER_HOST=unix:///var/run/docker.sock \ -e TESTCONTAINERS_RYUK_DISABLED=true \ internal-docker-repo/testcontainers-java-smoke:latestIt connected, reported Server Version: 29.7.1 and API Version: 1.55, ran the command, and printed its own success marker with a clean exit code. That's the actual proof: not “the daemon runs,” but “a real Testcontainers workload runs.”
What's left
Functionally, this is done. Unprivileged pod, isolated nested daemon, authenticated pulls through internal repos only, a real Testcontainers run passing. What's left is cleanup: stripping temporary debug logging out of the patched binaries and re-running all three checks against the cleaned build before it ships into shared CI images.Questions people actually ask
Does this need privileged: true? No, and that's really the whole point of using Sysbox instead of a DinD sidecar. Isolation comes from a real Linux user namespace, not from trusting the container not to misbehave. People also ask whether this works behind a fully air-gapped registry with no exceptions at all. It does, as long as the virtual repository actually mirrors what the test suite needs and the mounted credentials are current. The token failure above is the most common way this breaks in practice. A fair question: if nested Docker was working, why did Testcontainers still fail? Because the failure lived in the library's bundled client, not the runtime. Worth checking those two things separately rather than assuming a working daemon means a working test suite. One last question: is any of this GKE-specific? Some of it, yes. The Artifact Registry details and the node-labeling steps are GKE conventions. The runtime fixes themselves sit lower than that. They're about proc-filesystem handling and namespace passthrough, and they'd apply to any locked-down, no-egress Kubernetes environment regardless of which managed provider is running it. [table id=3 /] [post_title] => Part Three: Running Secure Docker-in-Docker on Locked-Down GKE [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => part-three-running-secure-docker-in-docker-on-locked-down-gke [to_ping] => [pinged] => [post_modified] => 2026-10-08 12:49:35 [post_modified_gmt] => 2026-10-08 12:49:35 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5307 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [2] => WP_Post Object ( [ID] => 5305 [post_author] => 15 [post_date] => 2026-09-23 15:22:22 [post_date_gmt] => 2026-09-23 15:22:22 [post_content] =>Part 2: Installing and Patching Sysbox for a Locked-Down Cluster
Part 1 covered why any of this is worth doing. This part is the actual runbook: what it took to get Sysbox running on a GKE cluster with no public internet access from any node or pod, reaching the outside world only through preconfigured virtual repositories in an internal Artifact Registry.Step 1: Install the base runtime
Standard stuff, at least on paper. Sysbox ships as a privileged DaemonSet that runs once per labeled node. It mounts host paths like /etc, /run, /usr/bin, /usr/local/bin, /var/lib, and the systemd unit directories, then runs an installer script that lays down the Sysbox binaries, the systemd services, and a node label. RBAC is minimal: a ServiceAccount, a ClusterRole scoped to get and patch on nodes, a ClusterRoleBinding tying the two together.kubectl label node <node-name> sysbox-install=yes kubectl apply -f rbac/sysbox-rbac.yaml kubectl apply -f runtime-class/sysbox-runtimeclass.yaml kubectl apply -f daemonset/sysbox-deploy-k8s.yaml Check it worked with: systemctl status sysbox sysbox-mgr sysbox-fs kubectl get runtimeclass sysbox-runc kubectl get nodes -l sysbox-runtime=runningIf all three services are active and the node carries the label, the base install is done. This part is genuinely easy. The rest of it isn't.
Step 2: Fix the installer for a node with no internet
Here's where the standard guidance stops applying. The stock installer script assumes it can reach the open internet to grab a few packages during setup. On a node with no outbound route at all, that assumption just doesn't hold, and it doesn't fail cleanly either. It hangs, or breaks somewhere unhelpful. The fix is a small overlay image. Rebase from an internal mirror of the installer image, add the one utility the deploy step actually needs (rsync, pulled through the internal registry rather than a public one), and swap in a patched installer script. The patched version stops assuming it can apt-install anything. Instead, it checks for the specific binaries Sysbox needs at runtime, fusermount3 and iptables, and fails immediately with a real error message if either is missing, instead of hanging while it tries to fetch them. It still runs the normal Sysbox checks around user-namespace procfs mounting and loading kernel modules like shiftfs when needed. This overlay approach isn't specific to Sysbox, either. Any DaemonSet installer that assumes internet access needs roughly this same treatment on a cluster that has none.Step 3: The first real failure
Base install healthy, services up, label present. Then the first actual Sysbox pod failed on sandbox creation. The error traced back to the runtime's rootfs handling, specifically mounting binfmt_misc onto proc/sys/fs/binfmt_misc. It turned out the sandbox's root filesystem simply didn't have that proc path yet, and the default mkdir followed by mount logic had no fallback for it.Step 4: Patch the runtime
This ended up touching two Sysbox components. In sysbox-runc, a dedicated procMount operation was added so binfmt_misc stops being handled like a normal rootfs mkdir followed by mount. Instead, the init helper remounts /proc, works from the namespace-aware /proc/1/root view, creates the destination there, and mounts it safely by file descriptor. Sysctl writes were also relaxed to tolerate a missing key, since some proc sysctl entries genuinely don't exist in this environment, and failing hard on that was pure noise. sysbox-fs needed a broader fix. A whole class of /proc/sys/* passthrough operations (lookup, open, read, write, readdir, readlink, setattr) were failing, and the real cause was that they weren't carrying enough process context into the namespace layer to correctly reproduce the caller's root, working directory, uid and gid, and capabilities. Once that context was attached, and the user namespace was deliberately stripped for generic proc-sys passthrough specifically, the permission and personality mismatches went away. A read-only filesystem edge case in temporary procfs mounting also needed a fallback instead of just failing outright. Both got rebuilt from source with multi-stage, multi-platform Dockerfiles, producing Linux amd64 binaries that replaced the host copies. Restart the services and it's done:systemctl restart sysbox sysbox-mgr sysbox-fs systemctl status sysbox sysbox-mgr sysbox-fsWith that in place, a basic Sysbox pod finally reached Running, and cat /proc/self/uid_map inside it showed a real user-namespace mapping. Small thing to check, but it's the tell that isolation is actually working and not just assumed. [table id=3 /] [post_title] => Part Two: Running Secure Docker-in-Docker on Locked-Down GKE [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => part-two-running-secure-docker-in-docker-on-locked-down-gke [to_ping] => [pinged] => [post_modified] => 2026-09-11 15:22:39 [post_modified_gmt] => 2026-09-11 15:22:39 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5305 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [3] => WP_Post Object ( [ID] => 5303 [post_author] => 15 [post_date] => 2026-09-15 15:21:55 [post_date_gmt] => 2026-09-15 15:21:55 [post_content] => Notes on getting Sysbox working on a GKE cluster with zero public internet access, so Testcontainers based tests can run inside the same pipeline as everything else.
Part 1: Why It Matters
I've watched a handful of platform teams hit this same wall. They lock down GKE the way it's supposed to be locked down: no public egress from any node or pod, every dependency routed through a small set of preconfigured virtual repositories in Google Artifact Registry that cover Docker, npm, and Maven. Security signs off. Compliance signs off. Everyone moves on. Then the test team shows up and asks why their Testcontainers based integration suite won't run in the pipeline. Testcontainers is the default way teams run integration tests against real dependencies. Spin up a real Postgres. A real Kafka broker. Run the test against it. Tear it down when you're done. It's not a mock or an in-memory stand-in, which is exactly why it catches bugs that mocks hide. The problem is easy to state and annoying to actually solve: Testcontainers needs a real Docker daemon to talk to. On a laptop, that's nothing. Docker Desktop is right there. Inside a Kubernetes pod on a shared, locked-down cluster, it's a much harder question, because a pod isn't a VM. It shares a kernel with everything else scheduled on that node. Two answers usually come up, and neither one is good. First option: privileged: true, the Docker socket bind-mounted in from the host, maybe a full DinD sidecar running privileged. It works. It also gives a test container a fairly direct line to the host kernel, and if that container gets compromised or misbehaves, the blast radius isn't contained anymore. Most security teams won't approve this, and honestly, they're right not to. Second option: give up on running the tests in the pipeline at all. Push them to a separate, less locked-down environment, or worse, back onto individual developer laptops. That undoes the entire point. You're right back to “passed on my machine, failed in CI” - the exact failure mode integration testing exists to kill.Where Sysbox actually helps
Sysbox is an open source runtime that sidesteps both bad options. A container running under Sysbox gets its own Docker daemon inside a real, isolated Linux user namespace. No --privileged flag, no host root access. The test container sees what looks like an ordinary Docker host, while the node just sees one more unprivileged pod, no different from anything else scheduled on it. That's the property that actually gets this past a security review. Not a promise that the workload will behave, but a real kernel-level boundary.Why this is worth the engineering effort
The value case, stated plainly: get Sysbox working on a locked-down GKE cluster and test teams run real Testcontainers based integration tests inside the same CI/CD pipeline as everything else, on infrastructure security already trusts. No exception requests. No separate environments to manage. No convincing anyone to sign off on a privileged pod. There's a second benefit that's easy to overlook. Once the cluster has this capability, every team building test infrastructure just inherits it. Nobody has to go through the privileged container question team by team, project by project. The next two parts get into how this actually gets built on a cluster with no internet egress: two runtime bugs that only show up in that kind of environment, and the exact checks that prove a real Java Testcontainers run worked end to end. [table id=3 /] [post_title] => Part One: Running Secure Docker-in-Docker on Locked-Down GKE [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => part-one-running-secure-docker-in-docker-on-locked-down-gke [to_ping] => [pinged] => [post_modified] => 2026-09-11 15:22:10 [post_modified_gmt] => 2026-09-11 15:22:10 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5303 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [4] => WP_Post Object ( [ID] => 5332 [post_author] => 15 [post_date] => 2026-09-10 14:07:20 [post_date_gmt] => 2026-09-10 14:07:20 [post_content] =>Keyva is pleased to announce the certification of the Keyva BMC Atrium Data Pump for the new ServiceNow Australia release. Clients can now seamlessly upgrade their ServiceNow App from previous ServiceNow releases (Zurich, Yokohama, Xanadu) to the Australia release.
The ServiceNow Australia release delivers enhanced AI-driven workflows, improved user experiences, and expanded automation capabilities to increase productivity, resilience, and service efficiency across the enterprise.
Keyva's BMC Atrium Data Pump provides synchronization of CIs, CI attributes, and relationships from the ServiceNow CMDB into the BMC Atrium CMDB. This integration allows organizations to leverage their existing investment in Enterprise Software and avoid costly "Rip and Replace" projects.
Learn more about the Keyva BMC Atrium Data Pump and view all the ServiceNow releases for which Keyva has been certified at the ServiceNow Store: store.servicenow.com.
[post_title] => Keyva BMC Atrium Data Pump ServiceNow to BMC Certified for Australia Release [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => keyva-bmc-atrium-data-pump-servicenow-to-bmc-certified-for-australia-release [to_ping] => [pinged] => [post_modified] => 2026-09-03 14:11:01 [post_modified_gmt] => 2026-09-03 14:11:01 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5332 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [5] => WP_Post Object ( [ID] => 5350 [post_author] => 15 [post_date] => 2026-09-09 16:29:47 [post_date_gmt] => 2026-09-09 16:29:47 [post_content] =>Software has moved well beyond its back-office origins. For most organizations today, it's the product, the primary customer touchpoint, or the system determining whether an order ships on time. As the stakes attached to application decisions continue to rise, so does the cost of getting them wrong.
Many organizations face an additional challenge: managing an older platform that still carries essential business logic, one that current staff no longer fully understand. Whether you're building something new or carrying an existing system forward, application development is what determines whether software becomes a long-term business asset or an accumulating liability.
We design, build, and modernize applications for organizations that depend on their software to perform reliably under real business pressure. The starting point differs from one engagement to the next, but the underlying discipline does not.
Discovery and Understanding: Where the Real Work Begins
A significant share of application projects go wrong before a single line of code is written. The problem the system was meant to solve was never fully understood in the first place. Engagements begin with the people who will actually use and depend on the system, rather than a predetermined list of assumed features. Time invested in discovery reduces the risk of building the wrong thing quickly and having to rebuild it later at greater cost.
Architecture receives the same level of attention. Transaction volume, regulatory requirements, and the way a system needs to interact with everything around it all inform the technical approach. Rather than defaulting to whichever pattern happens to be familiar or currently popular, we design based on actual need. A payment platform and an internal reporting tool carry different demands, even when it would be simpler to design them the same way.
Modernizing Legacy Systems: The Hidden Knowledge Problem
Legacy systems tend to carry more institutional knowledge than they appear to on the surface. A platform that has been in production for fifteen or twenty years typically encodes a substantial number of business rules that were never formally documented. Many were established through past incidents the organization has no interest in repeating.
Before any component is replaced, we invest time in understanding what the code is actually doing. This is often a different question than what the existing documentation describes. Modernization that skips this step risks discarding logic that was quietly load-bearing. This gap tends to surface only after the new system is already in production.
This is one reason engagements are delivered in stages rather than as a single large cutover. A comprehensive rewrite delivered all at once depends on every assumption being correct from the outset. This is rarely the case in practice. Delivering in smaller, working increments allows the business to see progress along the way, identify issues while they remain inexpensive to correct, and adjust direction before significant effort has been committed to a flawed assumption.
Data migration follows the same principle. Data is mapped, validated, and reconciled as it moves between systems. A migration that is technically complete but has quietly introduced data integrity issues has not truly succeeded, even if it appears to have.
Critical Considerations Often Overlooked
Integration Design Matters from Day One
Very few applications operate in isolation. A system that cannot integrate cleanly with the environment around it tends to become disconnected within a relatively short period. This requires additional work later to reconnect it, typically under less favorable conditions than if the integration had been designed in from the outset.
Quality Assurance Isn't a Final Step
Testing is subject to similar pressure, often deprioritized as deadlines approach. Building quality assurance into the development process from the beginning allows issues to be identified while they remain inexpensive to resolve. It also gives teams the confidence to release changes at a sustainable pace.
Modern Infrastructure Requires Modern Architecture
When a legacy system moves to modern infrastructure, the objective extends beyond relocation. Re-architecting the system to take genuine advantage of what a modern, cloud-native platform provides is what allows the application to scale with the business. Without this consideration, it becomes a constraint on growth instead.
How We Approach Custom Application Development
Most organizations we work with already employ capable engineers. What is typically in shorter supply is sufficient capacity, whether measured in headcount or available time. These constraints make it difficult to take on a substantial build or modernization initiative without disrupting existing priorities. This is generally where our engagement begins: working alongside your existing team rather than in place of it.
Your engineers remain engaged for the duration of the project, well beyond the initial kickoff. Knowledge is transferred in both directions. By the conclusion of the engagement, your team should understand the system well enough to operate it, extend it, and explain it to future hires. Every engagement includes formal training and documentation to support that outcome. A system your organization does not fully understand becomes its own form of technical debt over time.
Scope, Security, and Sustainable Success
We maintain transparency around scope. In some cases, a full rebuild is genuinely the right answer. In many others, a smaller and more targeted solution addresses the underlying business need. Part of working responsibly means recommending that option even when a larger engagement would be more advantageous to us commercially.
Progress is evaluated against whether the actual business problem is being resolved. This happens through regular conversations with the people who will ultimately depend on the result. Rather than tracking solely through delivery metrics that can appear favorable right up until launch and prove otherwise afterward, we focus on outcomes that matter.
Security is treated as an integral part of development rather than a separate, later phase. Depending on the industry and the sensitivity of the data or transactions involved, this typically includes secure coding practices, access controls, and applicable compliance requirements addressed from the earliest stages of the project. The team responsible for planning the work is also the team that builds and supports it. Recommendations are grounded in prior delivery experience rather than theoretical best practice.
Application Development Across Industries
Our teams have delivered this kind of work in financial services, retail, industrial and agricultural operations, and healthcare. We've worked on systems ranging from customer-facing platforms processing significant transaction volume to internal tools that never reach an end customer directly. Regulatory requirements and tolerance for downtime vary meaningfully across these industries, but the underlying approach remains consistent.
If your organization is evaluating a new build, a modernization initiative, or simply needs additional capacity on something business-critical, we would welcome the conversation.
[table id=3 /]
[post_title] => Application Development and Software Modernization: Building Systems That Drive Business Results [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => application-development-and-software-modernization [to_ping] => [pinged] => [post_modified] => 2026-09-09 16:29:47 [post_modified_gmt] => 2026-09-09 16:29:47 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5350 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [6] => WP_Post Object ( [ID] => 5327 [post_author] => 15 [post_date] => 2026-09-08 13:59:03 [post_date_gmt] => 2026-09-08 13:59:03 [post_content] =>Keyva is pleased to announce the certification of the Keyva BMC Atrium Data Pump for the new ServiceNow Australia release. Clients can now seamlessly upgrade their ServiceNow App from previous ServiceNow releases (Zurich, Yokohama, Xanadu) to the Australia release.
The ServiceNow Australia release delivers enhanced AI-driven workflows, improved user experiences, and expanded automation capabilities to increase productivity, resilience, and service efficiency across the enterprise.
Keyva's BMC Atrium Data Pump provides synchronization of CIs, CI attributes, and relationships from the BMC Atrium CMDB into the ServiceNow CMDB. This integration allows organizations to leverage their existing investment in Enterprise Software and avoid costly "Rip and Replace" projects.
Learn more about the Keyva BMC Atrium Data Pump and view all the ServiceNow releases for which Keyva has been certified at the ServiceNow Store: store.servicenow.com.
[post_title] => Keyva BMC Atrium Data Pump BMC to ServiceNow Certified for Australia Release [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => keyva-bmc-atrium-data-pump-certified-for-australia-release [to_ping] => [pinged] => [post_modified] => 2026-09-03 14:10:51 [post_modified_gmt] => 2026-09-03 14:10:51 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5327 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) [7] => WP_Post Object ( [ID] => 5324 [post_author] => 15 [post_date] => 2026-09-04 13:57:23 [post_date_gmt] => 2026-09-04 13:57:23 [post_content] =>Keyva is pleased to announce the certification of the Keyva HP Universal CMDB Data Pump for the new ServiceNow Australia release. Clients can now seamlessly upgrade their ServiceNow App from previous ServiceNow releases (Zurich, Yokohama, Xanadu) to the Australia release.
The ServiceNow Australia release delivers enhanced AI-driven workflows, improved user experiences, and expanded automation capabilities to increase productivity, resilience, and service efficiency across the enterprise.
Keyva's HP Universal CMDB Data Pump provides synchronization of CIs, CI attributes, and relationships from the ServiceNow CMDB into the HP Universal CMDB. This integration allows organizations to leverage their existing investment in Enterprise Software and avoid costly "Rip and Replace" projects.
Learn more about the Keyva HP Universal CMDB Data Pump and view all the ServiceNow releases for which Keyva has been certified at the ServiceNow Store: store.servicenow.com.
[post_title] => Keyva HP Universal CMDB Data Pump Certified for Australia Release [post_excerpt] => [post_status] => publish [comment_status] => closed [ping_status] => closed [post_password] => [post_name] => keyva-hp-universal-cmdb-data-pump-certified-for-australia-release [to_ping] => [pinged] => [post_modified] => 2026-09-03 14:10:37 [post_modified_gmt] => 2026-09-03 14:10:37 [post_content_filtered] => [post_parent] => 0 [guid] => https://keyvatech.com/?p=5324 [menu_order] => 0 [post_type] => post [post_mime_type] => [comment_count] => 0 [filter] => raw ) ) [post_count] => 8 [current_post] => -1 [before_loop] => 1 [in_the_loop] => [post] => WP_Post Object ( [ID] => 5363 [post_author] => 15 [post_date] => 2026-11-11 22:27:59 [post_date_gmt] => 2026-11-11 22:27:59 [post_content] => We've noticed that several of our retail clients are building new applications, or modernizing existing ones, that center on customer experience. The returns process is a key part of those applications: it supports retail operations and shapes customer satisfaction. We've built a demo application, Returns Desk, that addresses a core need in that process: deciding each return request quickly, consistently and at a known cost, using a language model only for the one step that needs it, reading what the customer wrote or photographed. The code, tests, sample data and Azure setup are public at github.com/keyva/returns-desk. It's relevant to anyone planning to put generative AI into a customer-facing process, because where the model sits decides what the process costs, how far it can be trusted, and who answers for each decision. Most of a business process should never reach a language model. The useful work is finding the one step that genuinely needs one, and building everything around it as ordinary, testable code. When teams first put generative AI into a workflow, the temptation is to hand the model the whole job: read the request, apply the policy, work out the refund, write the reply. It demos well and fails quietly. The model is slow and costs money on every call, and it can't promise to get the arithmetic right twice in a row. Worse, nobody can say which rule it applied. We built Returns Desk to show the alternative on a process every retailer runs. It is the returns desk of Larkfield Home & Apparel, a fictitious retailer of kitchenware and clothing. Customers never see the desk itself: it is the back-office layer behind a self-service returns portal, where each request is approved, priced or sent to a person. The question it answers is simple: where exactly does the model belong?The demo: a returns desk with one hard question
A customer asks to send an item back. They name the order and the item, and either pick a reason from a list or explain in their own words, often with a photo. Larkfield has to decide whether to refund, replace, deny or escalate, and who pays for the return. Almost all of that is policy, and policy is a table. The return window, which categories can come back, when a photo is required, the per-quarter limit, the fee: each fits in a cell. Only one question has no cell, because nobody typed the answer into a field: who is responsible for the problem? Was it the retailer, the carrier or the customer, or is it unclear? Answering it means reading what a person wrote and looking at what they photographed. We used one test to draw the line. If an intern could write the rule in an afternoon from the policy document, it is code. If the answer depends on reading what a person wrote or looking at a picture, it is the model. How a return request moves through the desk Policy turns away or settles most requests before a model is involved; only a customer's own words reach the engines, and nothing takes effect until the validator has checked it.What the rules handle: most of it, for free
Every rule Larkfield has lives in one small JSON file that fits on a slide. It sets a 30-day window counted from the carrier's delivery date, three returns per customer per quarter, and categories such as perishables and final-sale items that can't come back at all. A table says, for each category and responsible party, which outcomes are allowed, what fee applies and who pays return postage. Policy checks every request before any model sees it, and many never go further:- A clearance throw blanket marked final sale is denied because final-sale items can't come back. No model is called and nothing is billed.
- A jacket returned 47 days after delivery is denied on the window, with a reply that cites the rule.
- A T-shirt returned with the reason "changed my mind" maps straight to the customer, who gets a refund. There is nothing to read, so no model is needed.
What the models handle: one question, asked two ways
When a customer explains in their own words, the request goes to two engines on Microsoft Foundry, both running the same model. They are asked exactly one question: who is responsible?- The generative engine reads the statement and the photo. It answers with a responsible party, a one-sentence reason for the clerk, a draft reply to the customer, and any flags it noticed, such as damage in transit or possible abuse. Its output follows a fixed schema, so the code never parses free text.
- The probabilistic engine uses Foundry's Decisions API to return a probability for each of the four parties and a confidence, with no prose. The probability for the named party is what lets policy set a floor for trusting the answer.
Guardrails: the engines read, the code decides
A request is approved without a person only when every condition in policy holds:- Both engines name the same responsible party.
- The probabilistic engine gives that party at least 80%.
- The refund is $75 or less.
- No blocking flag is raised, such as possible abuse or signs of use.
- The customer is under their per-quarter limit.
Measuring it: labeled requests, not impressions
A model in a business process needs a number behind it, not a good feeling from the demo. Returns Desk ships with 46 hand-written requests whose answer is already known. Forty include a customer statement, ten for each responsible party, written with the variety real customers bring. The other six carry only a reason code. An evaluation runs both engines over every labeled request. It reports how often each engine named the known party, a grid of known party against named party, and the cost per request. In production, each resolution a clerk confirms would become a new labeled request, so the measurement could grow with use. The demo only re-scores its own sample set. Two choices kept it honest. We wrote the statements by hand rather than generating them, so the test doesn't measure how well one model reads another model's writing. And we left out claims about how well-calibrated the probabilities are, because 40 requests are too few to support them. That makes the 80% floor a starting setting, not a proven one. Tune it against labeled requests before trusting it with money.What changes at enterprise scale
The split between rules and model holds at any size. What a production rollout adds is everything around it:- Requests arrive from the returns portal and the contact center. Approved refunds go to the payment platform, and carrier cases go to a claims process instead of stopping at a label.
- Identity and audit. Every resolution records which clerk approved it, from the same sign-in that guards the board. Policy changes go through change control like any other release.
- Many clerks work the queue at once, and the resolution log lives in a database rather than a file. Engine calls are made only for requests with a statement, so cost grows with the share of returns that need reading, not with total volume.
- Measurement on real returns. The engines are evaluated on the retailer's own labeled returns. Auto-approval runs in shadow mode first, logging what it would have done next to the clerk's decision, before any limit is raised.
Takeaways for your own processes
The pattern carries well beyond returns: claims, support tickets, invoice exceptions, access requests. Wherever a person's words meet a set of rules, the same split applies.- Find the one question. List every decision in the process and apply the intern test. Usually only one or two need a model.
- Put the rules in data. A policy file the business can read and edit beats rules buried in a prompt, and it costs nothing to run.
- Ask the model for an input, not a decision. A responsible party with a reason is something code and people can check. A finished outcome isn't.
- Let code bound the risk. Caps, allowed outcomes and arithmetic checks hold no matter what the model says or what a customer writes to it.
- Keep a person on the hard cases. Automation should clear the easy, agreed, low-value requests, so the clerk only sees what needs judgment.
- Measure before you trust. A labeled set and a repeatable evaluation turn "it seems to work" into accuracy and cost per request.
Try it yourself
Returns Desk is open source under the MIT license at github.com/keyva/returns-desk.- No cloud account: clone it and run the tests. They use canned engine answers and never call Azure.
- The full demo: you need an Azure subscription, uv and OpenTofu. The included OpenTofu sets up the Foundry resources with Microsoft Entra ID sign-in and API keys turned off. The README walks through running the board locally and deploying it to Azure Container Apps. The hosting steps haven't been run end to end yet, so treat them as the intended order rather than a tested script.
When VMware Stopped Being the Safe Choice
Where the Model Belongs: Lessons from a Returns Desk
Part Three: Running Secure Docker-in-Docker on Locked-Down GKE
Part Two: Running Secure Docker-in-Docker on Locked-Down GKE
Part One: Running Secure Docker-in-Docker on Locked-Down GKE
Keyva BMC Atrium Data Pump ServiceNow to BMC Certified for Australia Release

Application Development and Software Modernization: Building Systems That Drive Business Results
Keyva BMC Atrium Data Pump BMC to ServiceNow Certified for Australia Release